
AI Content Credibility Risks in Procurement Evaluations
Vendors must make claims verifiable by AI agents, not just persuasive to humans.
October 29, 2026
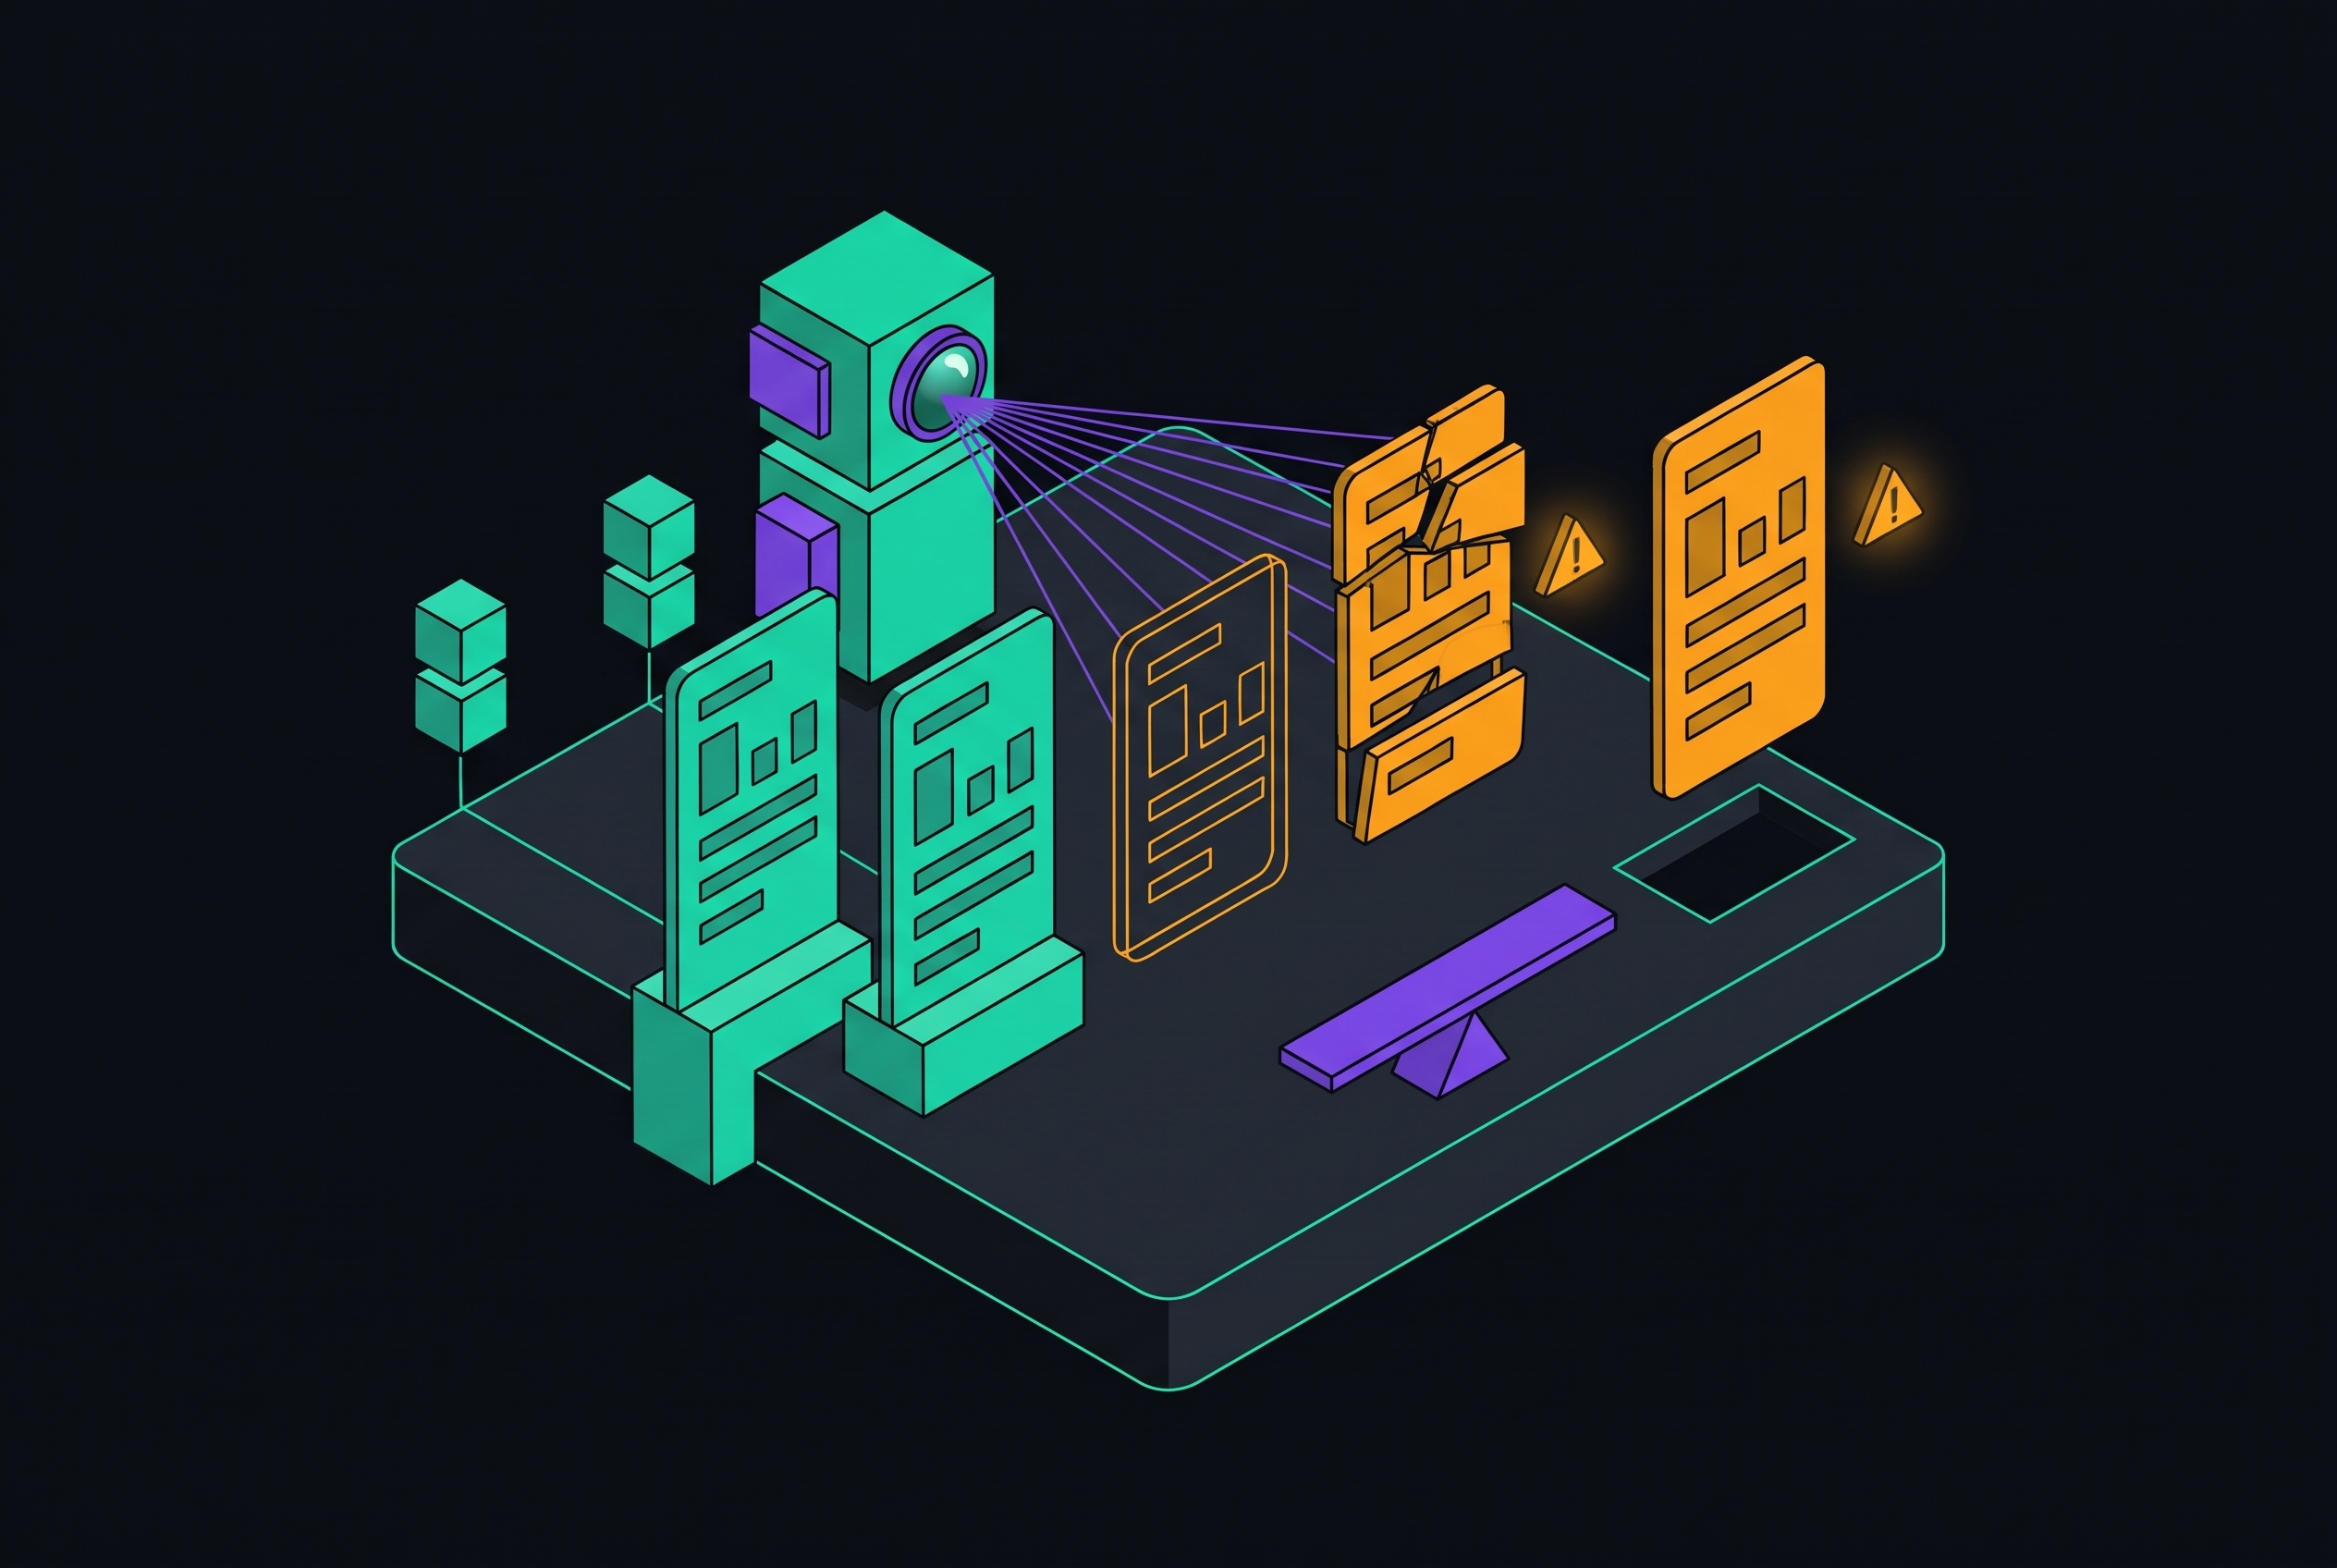
AI content credibility risks in procurement evaluations arise when an agent cannot independently confirm a vendor’s claims. As agents take on B2B software evaluation, verifiability becomes the defining requirement for procurement-stage content. Persuasive claims may attract attention, but accessible, current and independently confirmable evidence is what allows a vendor to survive scrutiny.
How AI procurement agents evaluate vendors — and why the evaluation is harder to game than any human review
A procurement officer types a natural-language instruction, and an AI agent returns a ranked shortlist. Vendors excluded from that list may never know they were evaluated. Between the instruction and the answer, the agent scans indexed repositories, eliminates irrelevant options and builds a feature matrix from public technical documentation. No sales call or demo is required. The evaluation can proceed without an SDR touchpoint or an opportunity for the vendor to explain its offer.
This capability developed through three phases, moving from information retrieval to comparison synthesis and then autonomous execution. The third phase changes the vendor’s role because the agent can conduct the evaluation. It cross-references structured supplier data, third-party review platforms, earned media mentions and independent sources. The vendor’s website is only one input. Its account of the product is assessed against information the vendor does not control.
That breadth makes the process harder to influence through presentation alone than a human review. A human buyer might call to fill in a missing field or sort out descriptions that conflict. An agent can instead move immediately to the next vendor when required information is incomplete or unverifiable.
Why evaluation — not discovery — is now where B2B software deals are won or lost
G2’s 2026 Buyer Behavior Report found that evaluation is the longest stage of the buying journey for the largest share of buyers. Forty percent identify it as the longest, ahead of research and decision. Buyers are spending more effort gathering proof than canvassing options. AI has reduced the friction of discovery, but it has not removed the work of deciding which recommendations deserve confidence.
The report also found that more than four in five buyers sourced software recommendations from an AI chatbot in the last two years. Among those buyers, half say AI had the most influence during shortlisting and evaluation. Its influence extends beyond initial discovery.
The vendors present when evaluation begins are almost always those involved in the final decision. That persistence makes the evidence available during evaluation commercially consequential, because exclusion may happen before a vendor can answer objections directly. Vendors still need to be found, but being seen alone cannot earn them a place in the decision. The competitive bottleneck has moved to whether a vendor can withstand scrutiny once found.
What AI agents actually scrutinize — and what they systematically discount
Structured data completeness is the first gate. Agents parse schemas and follow semantic markup. Pricing structures, service tier definitions, compliance certifications, integration compatibility and API documentation must be available in a form the agent can read. Visual hierarchy cannot fill a missing field. Benefit-focused copy may persuade a person, but it does not supply the comparable specifications needed for evaluation.
The authority of third-party citations is a second gate. Agents weight recommendations through the frequency and authority of independent citations, rather than the frequency with which a vendor repeats its claims. Earned mentions and data from review platforms give agents more to draw on than the vendor’s own account. Repetition is not independent corroboration. When a vendor puts a claim on several assets it controls, the evaluator still has only the same source to go on.
Within those inputs, specificity determines what can be assessed. Vague value propositions become noise, generic narratives are filtered out, and missing mandatory requirements can trigger disqualification before scoring begins. Concrete outcomes, explicit timelines and measurable before-and-after comparisons give the agent something to evaluate. Access imposes another constraint on otherwise useful evidence. Gated implementation guides, API documentation and technical specifications have significantly reduced citation value because an agent cannot ordinarily reach the material behind a form.
These mechanisms distinguish unreadable evidence from unsupported claims, but both can leave a vendor without a usable signal. One fails at access or parsing. The other reaches the evaluator but fails when checked.
The specific credibility risks that unverifiable vendor claims create
A prospect asks an AI whether a platform supports a specific capability. The model says no because the documentation sits behind a form or has not been indexed, although the platform has supported the capability for years. The prospect moves to a competitor. The vendor gets no form fill and never knows there was a chance to win the deal. This hallucination-as-lost-deal scenario exposes the asymmetry of agent-mediated evaluation, in which a false answer can end consideration without creating a conversation.
Stale records create a different route to the same problem. Review platforms, comparison pages and partner directories can still have profiles from several years ago that rank in search and feed model training data. Pricing may have changed, integrations may have expanded or compliance certifications may have been updated. The agent may nevertheless cite the old version as current. A vendor can therefore be assessed against a product description it no longer recognizes.
Invisibility is a separate failure from inaccurate representation. When incomplete or unstructured data prevents assessment, the agent can skip the vendor entirely before scoring. Conventional marketing cannot win back a deal the vendor never knew about.
The risk also runs toward the buyer. G2’s reporting found that buyers come across AI-generated information about vendors that is wrong, so human reviewers must fact-check the claims. Shortlisting does not end the credibility test. A vendor that passes the automated stage can still lose confidence during human review if the evidence behind the recommendation cannot be confirmed.
Why traditional social proof formats fail at both failure points
Case studies were designed to explain success and shift human perception. They are usually static, retrospective narratives written by the vendor about the vendor. An agent has no independent mechanism to confirm the outcomes merely because the narrative describes them precisely. Specificity can improve the account without authenticating it. The same limitation confronts a buyer checking the agent’s recommendation.
Logo walls and testimonials have a related weakness. They assert a relationship or endorsement without supplying a chain of custody. In their traditional form, no third party issues them, no cryptographic signature binds them to a specific customer and time, and no live source establishes their present status. The logo identifies a claimed association. It does not establish which capability the customer used or whether the relationship remains current.
Even an ungated case study PDF may be unindexed, unstructured or unverifiable, making access alone an insufficient remedy. Static assets also grow out of date without a clear warning. A case study published two years ago may describe a customer who has since churned, a changed feature set or a pricing model that no longer exists.
Traditional analyst influence presents a further mismatch with the evaluation channel. Analyst reports are used by a small and shrinking share of buyers, weakening the alignment between analyst-centric spending and how agents form recommendations. Neither establishes the independent, current evidence needed for automated selection and subsequent human review.
What verifiability actually requires in an agent evaluation context
Verifiability has three distinct requirements, which are machine-readability, independent confirmability and currency. Machine-readability means that an agent can consume the evidence without interpreting a landing page’s persuasive design. Schema.org markup, publicly indexed technical specifications, API documentation and parseable pricing data serve that requirement. Structure makes the claim available for assessment. It does not, by itself, establish that the claim is true.
Independent confirmability requires a way to check a claim without relying only on the vendor’s word. Third-party citations, earned media mentions and review platform data provide corroboration outside vendor-owned content. Cryptographic attestation extends that principle by supplying a signature as a verification mechanism that makes the integrity and origin of a claim mathematically checkable. The scope of the signed claim still determines what the evidence establishes.
The W3C Verifiable Credentials Data Model v2.0 sets standards for credentials that are cryptographically secure, respect privacy and are machine-verifiable. An agent can check them without contacting the original issuer. Related uses of cryptographic attestation span email sender authentication, web server agent identity, media file provenance and software build integrity.
Currency requires evidence of how things stand now for the claim being checked. Proof that was accurate at publication can actively mislead both an agent and the human reviewing its output if conditions have changed. Dynamic, live-linked proof addresses the stale-record failure by updating the state available for evaluation.
Feature-level and customer-level proof as the operative unit of verifiable evidence
Company-level reputation is too coarse to answer a capability-specific procurement question. An agent needs to assess whether a vendor can deliver a particular capability to an organization like the buyer’s. Generic customer-since claims and aggregate satisfaction scores do not establish that connection. The operative unit is more specific. It is a customer using a defined feature set during a defined period, with a measurable result and an independent verification path.
That granularity follows from the comparison process itself. Agents rely on field-level data that can be assessed across vendors, so a claim must map to the capability under review. A broad endorsement cannot take the place of an integration specification or proof that a feature is used. Without that mapping, the claim gives the agent nothing to compare with other vendors.
Letterprove provides a practical application of signed, usage-backed proof, with an important boundary. Its approach observes customer product usage and publishes signed attestation endpoints backed by customer counts, vendor feature usage data and live usage data. Letterprove’s public proof gives counts without naming customers, and its per-customer documents and chains are no longer in use. That distinction limits what the public endpoint establishes. It illustrates machine-verifiable attestation, but aggregate usage evidence is not equivalent to named, customer-level outcome proof.
Building this infrastructure is not equally easy for every vendor. Systems such as BIMI brand indicators and build-level attestation can call for registered trademarks or enterprise CI platforms that are hard for smaller operators to support. The resulting complexity favors larger vendors and those that invest early. As procurement evaluation depends more heavily on verifiable evidence, that early investment can compound into a structural advantage.
How vendors should reframe their proof strategy for agent evaluation — starting now
The practical response is to change how proof is produced, published and maintained, beginning with an audit. Identify every proof asset in use and ask whether an agent can independently confirm what it asserts. Treat logo walls, static testimonials, gated case studies and unverifiable PDFs as human-facing collateral. Keep the distinction explicit. An asset can help a person understand the product without qualifying as independently checkable evidence.
Make API documentation, compliance certifications, integration specifications and pricing structures ungated, schema-marked and crawlable. This work belongs to engineering and content operations as well as marketing because the agent needs accessible, parseable publication architecture to reach and parse the evidence. Copy changes cannot solve inaccessible technical documentation. The goal at this stage is to make required facts available for comparison.
Then build the independent citation footprint that supports confirmation. Invest in earned media, review platform presence and authoritative publisher relationships that generate citations outside vendor control. Those sources give agents a basis for corroboration rather than another version of the vendor’s assertion. Independence is the essential distinction here.
Finally, move toward dynamic, machine-readable attestation tied to live usage data, while keeping each claim at the granularity its evidence supports. Signed endpoints such as Letterprove’s represent this category, but the proof strategy should distinguish aggregate counts from customer-specific evidence. The target is a defined customer, feature, outcome and date that can be verified at evaluation time. Build toward that standard before agentic procurement becomes the main way buyers buy. Credibility infrastructure established early can secure shortlist positions that latecomers struggle to displace, making verifiable proof a distribution moat.